Working with agents
Benchmark: the same AI with and without Pragma
What we tested in November 2026, how, every result including the weak ones, and what the results do and do not show.
On 5 November 2026 we gave the same requests to the same AI models twice: once on their own, and once inside Pragma. Nothing in the requests was changed between runs, and a script, not a person, checked every result. This page has the method, every task and its exact wording, every score (the good ones and the bad ones), pictures of the real outputs, and the limits of what it shows.
The short version:
- A free AI on an ordinary graphics card goes from zero to finished work. Qwen3.5 35B in a plain chat saved no files at all. In Pragma it saved a file for 9 of 9 post, website and PDF requests.
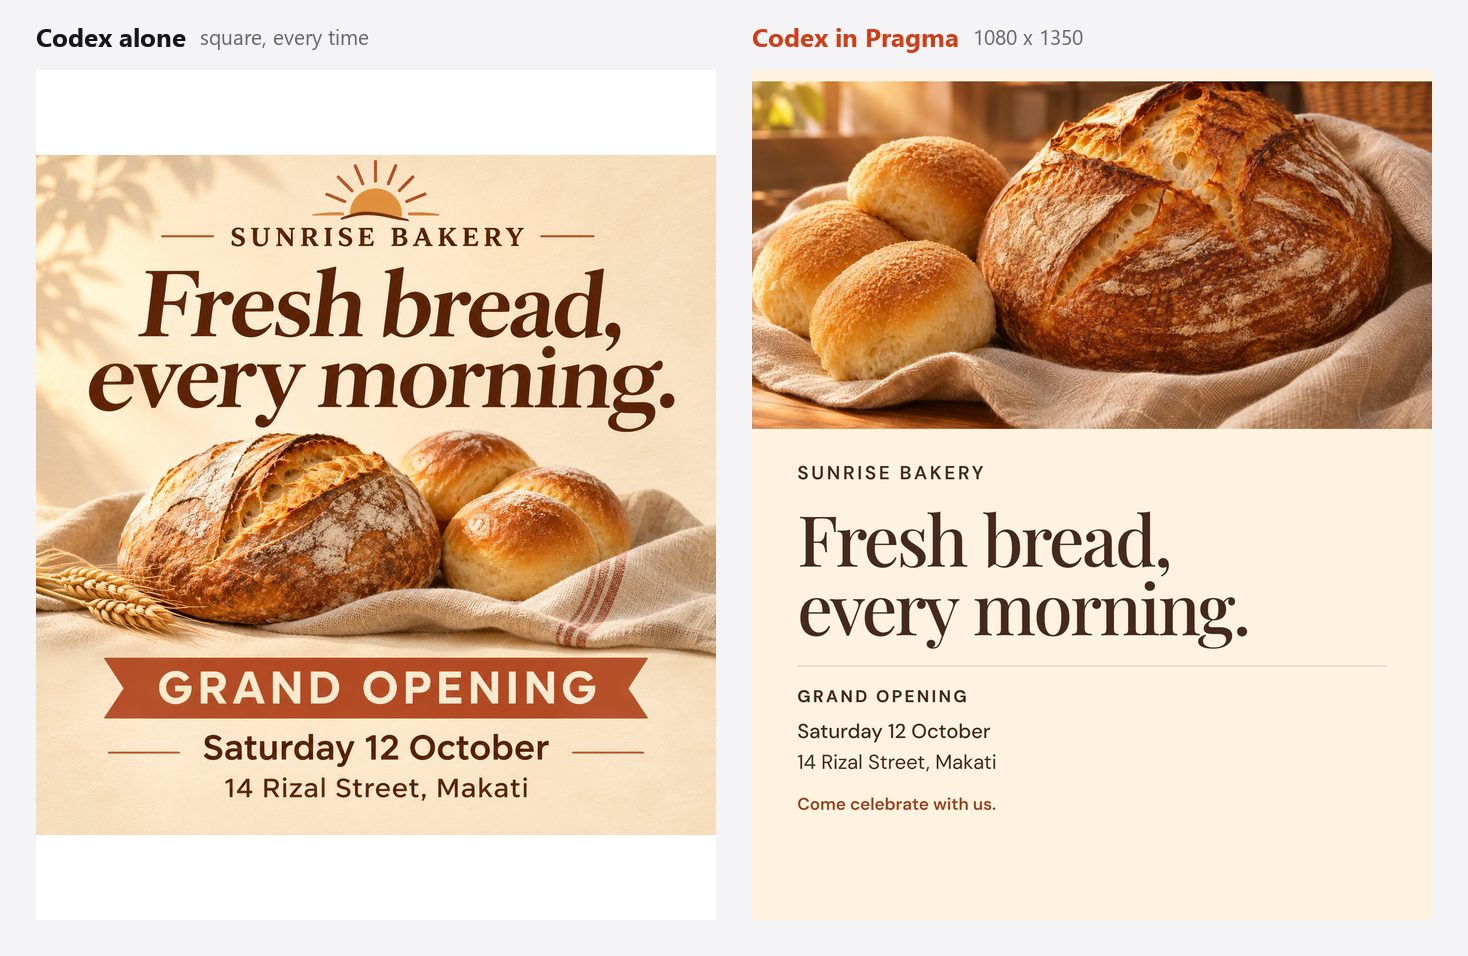
- Pragma keeps the rules of the job. Codex on its own made square posts when the request needed 1080 by 1350, and could not say what we worked on yesterday. In Pragma it got both right every time.
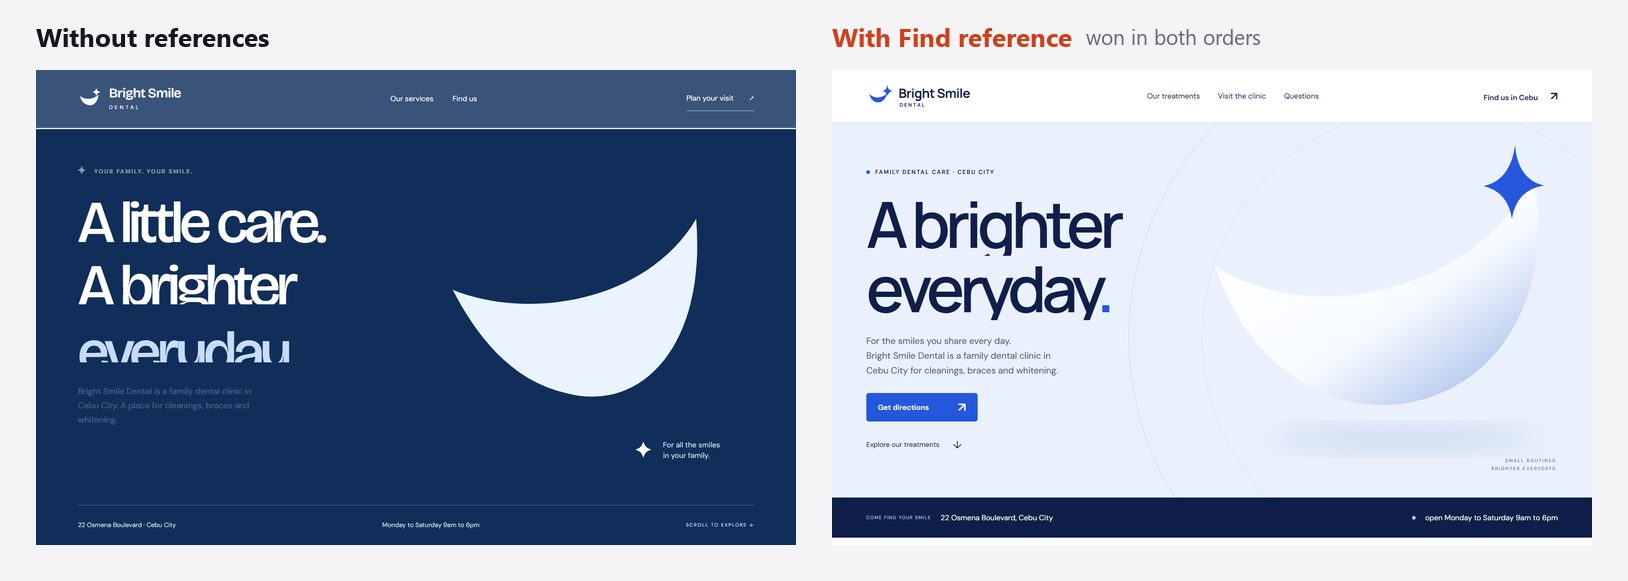
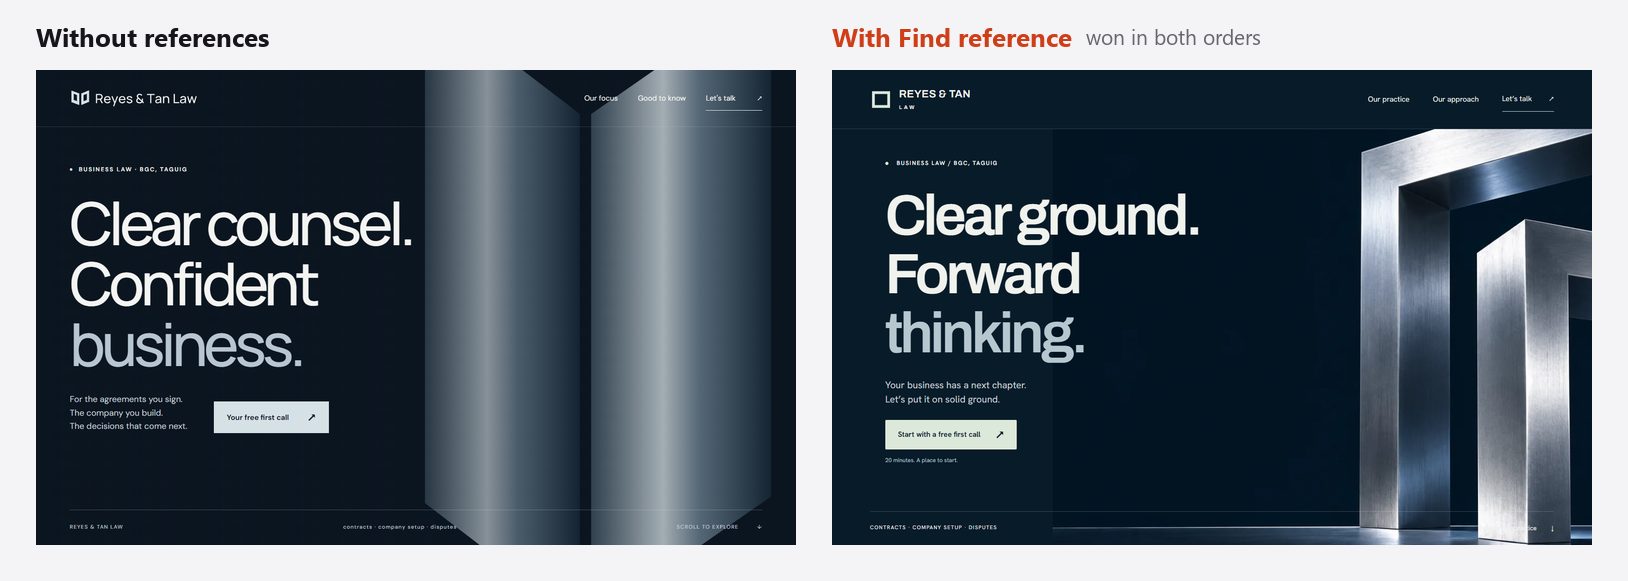
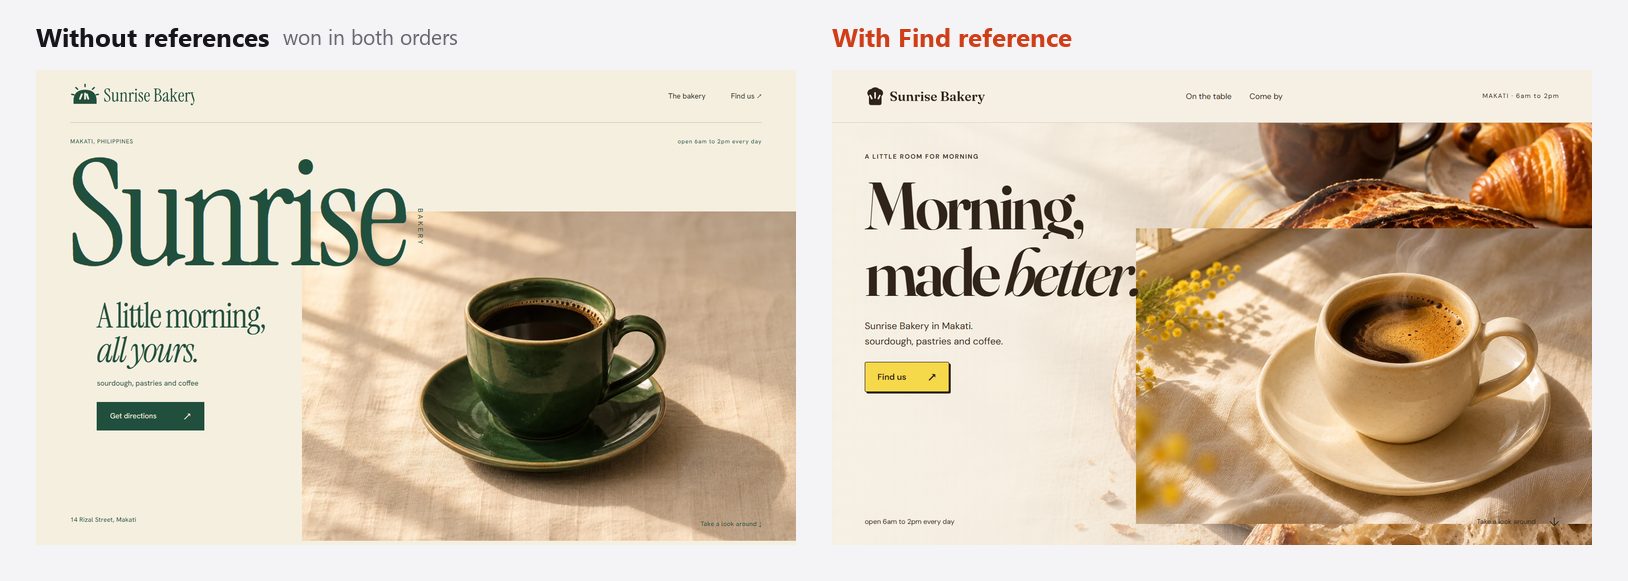
- Pages designed with Find reference were judged better in 12 of 18 blind comparisons.
- It is not a win everywhere. On most other jobs Codex did as well on its own, and Pragma takes longer on a website because it asks questions and reviews the page before it says done.
What we compared
| Setup | What it is |
|---|---|
| Qwen3.5 35B, plain chat | The model in llama.cpp's own chat page. It can only answer in words. |
| Qwen3.5 35B, Qwen Code alone | The same model in Qwen Code, an agent that can use files and tools, without Pragma. Run once, on the post, as a control. |
| Qwen3.5 35B, in Pragma | The same model file and settings as a Pragma companion in auto mode. |
| Qwen3.5 9B, plain chat and in Pragma | A smaller free model, the same way, one run each. |
| Codex alone and in Pragma | GPT-6 Astra, in its own command-line app, then as a Pragma companion. |
| Antigravity alone | Gemini 4 Argon in its own app, for reference. Its Pragma runs were cut short (see the limits below). |
All of it ran on one Windows computer with an RTX 5070 (12 GB of graphics memory) and 64 GB of memory, on Pragma 1.3.71 Beta. The local models ran in llama.cpp with the same model files, context window and settings in every setup. Each request ran up to three times. Every run started from an empty folder with only the request typed. When Pragma asked a question or showed a choice, the test gave one fixed reply or took the first option, the same every time.
The tasks, word for word
| Task | The request |
|---|---|
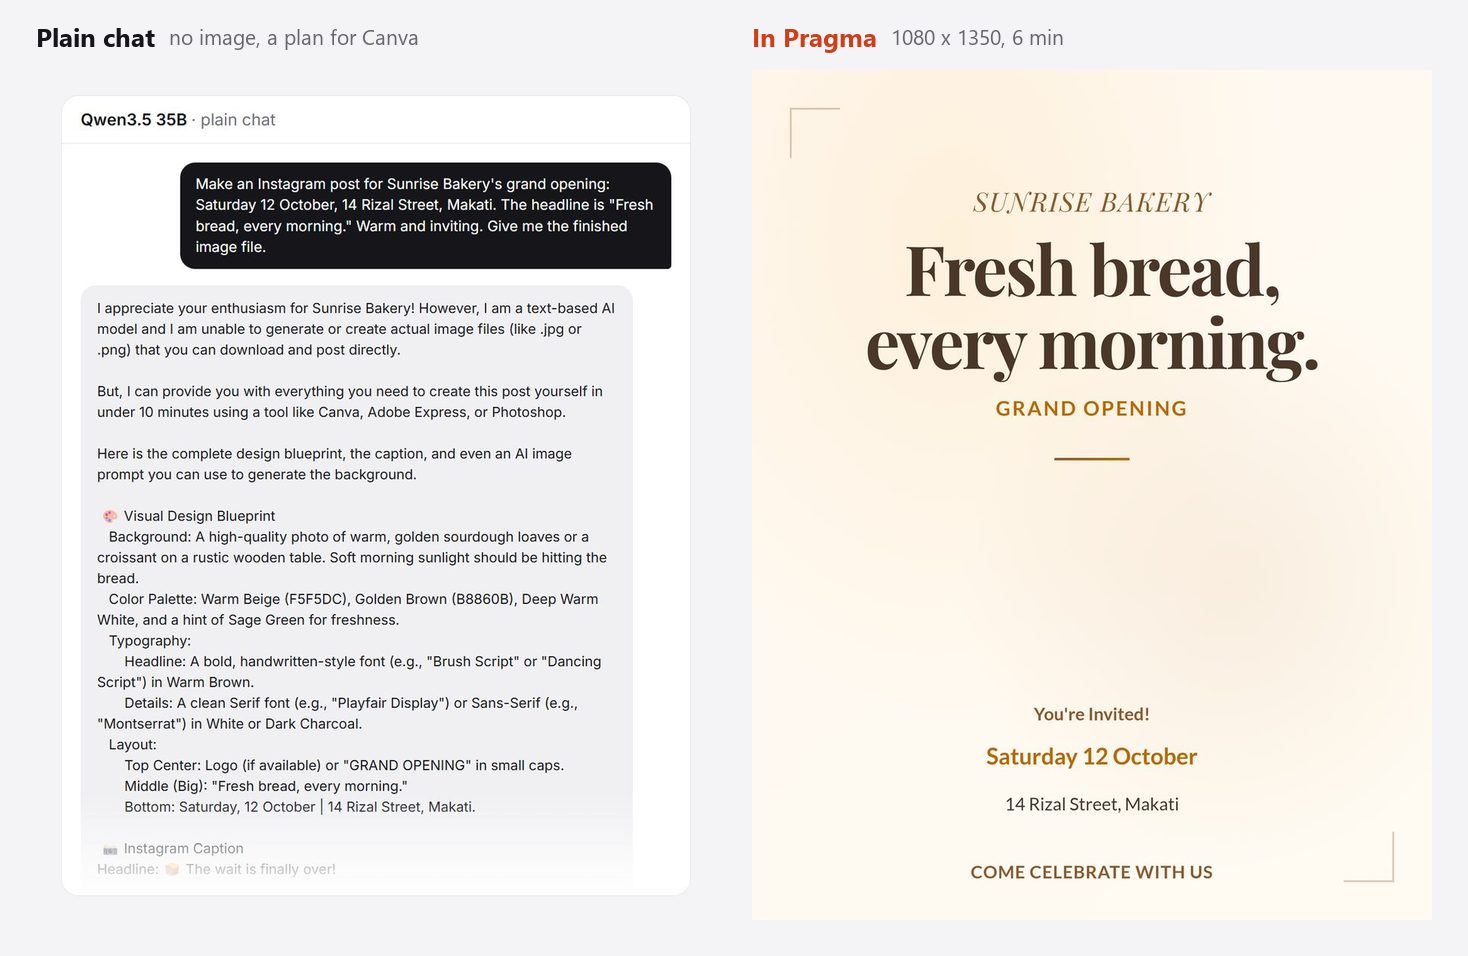
| Poster | Make an Instagram post for Sunrise Bakery's grand opening: Saturday 12 October, 14 Rizal Street, Makati. The headline is "Fresh bread, every morning." Warm and inviting. Give me the finished image file. |
| Video | Make a 6-second vertical video for Sunrise Bakery that counts up to 1,000 and then says "loaves baked this week". Give me the finished video file. |
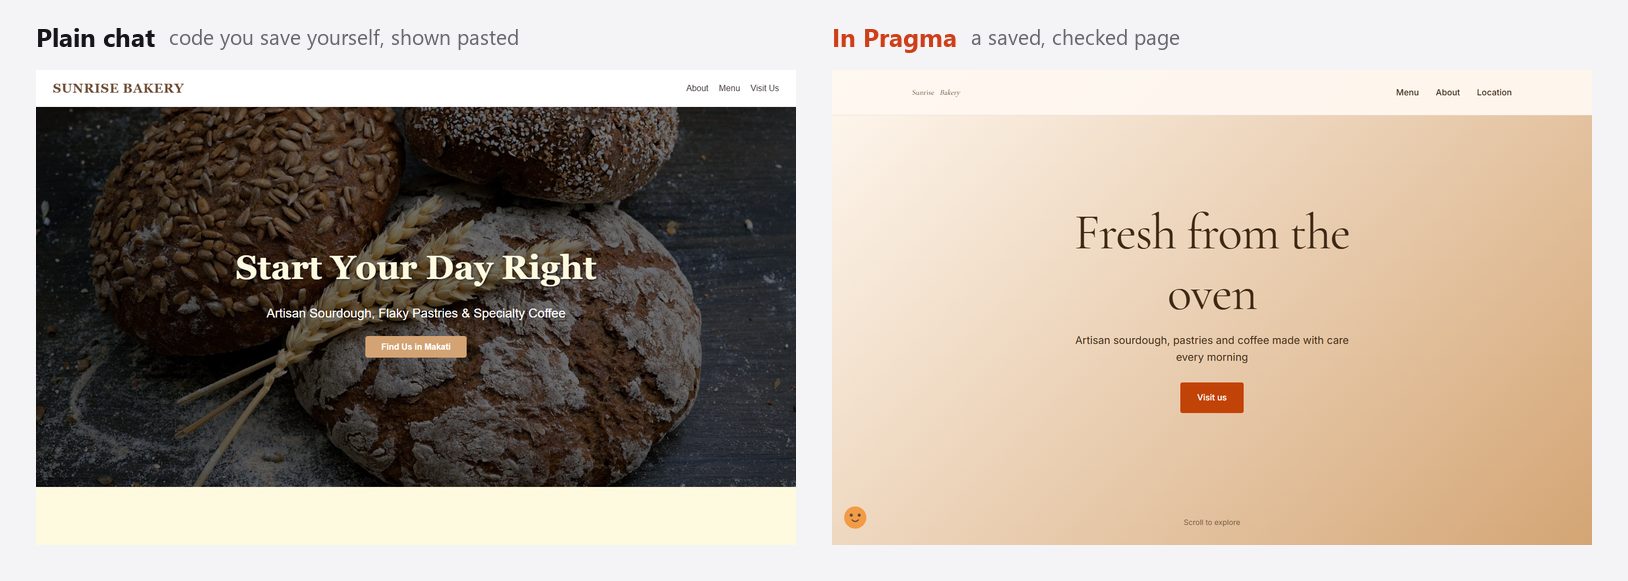
| Website | Build a one-page website for Sunrise Bakery: sourdough, pastries and coffee, open 6am to 2pm every day, at 14 Rizal Street, Makati. Give me the finished page. |
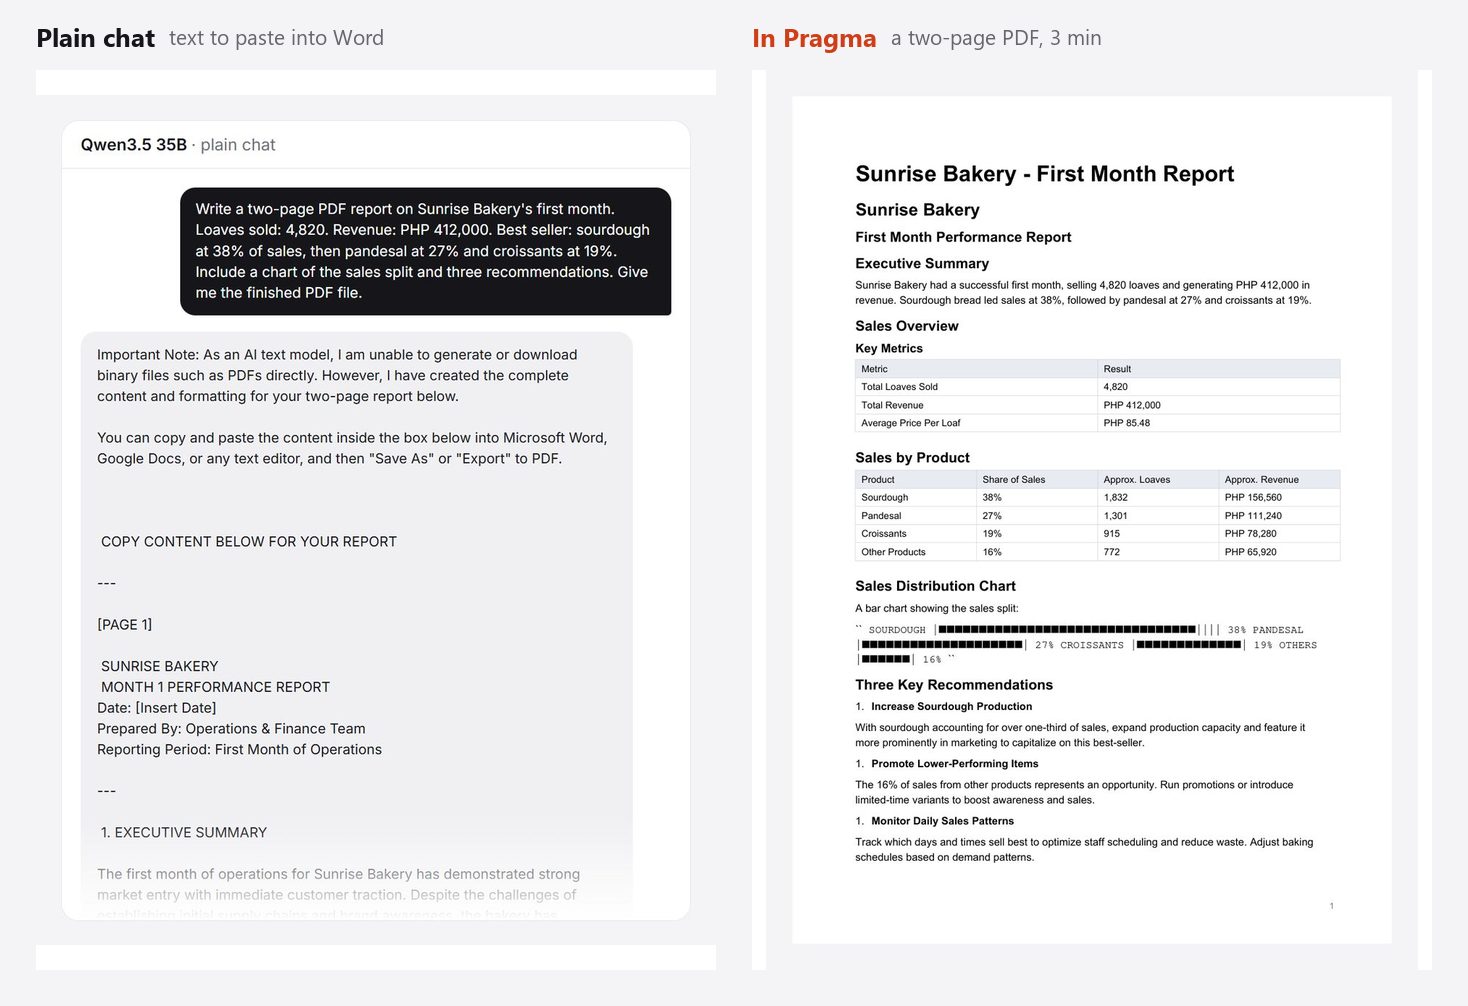
| PDF report | Write a two-page PDF report on Sunrise Bakery's first month. Loaves sold: 4,820. Revenue: PHP 412,000. Best seller: sourdough at 38% of sales, then pandesal at 27% and croissants at 19%. Include a chart of the sales split and three recommendations. Give me the finished PDF file. |
| Web search | What was the population of Makati in the 2020 Philippine census? Give me the number and at least two sources with working links. |
| Spreadsheet | Make an Excel spreadsheet of Sunrise Bakery's sales this week. Monday 612, Tuesday 588, Wednesday 640, Thursday 701, Friday 820, Saturday 955, Sunday 704 loaves. Add a total row that uses a formula and a chart of the week. Give me the finished .xlsx file. |
| Remember | Who is our flour supplier and when do they deliver? (Asked in a new chat. The answer was given in an earlier one.) |
| Find a file | Somewhere on this computer there is an invoice from Acme Packaging from October. Find it and tell me the total amount due and where the file is. |
| Schedule | In 3 minutes from now, and then every day at that same time, write a file called daily-note.txt in your working folder with today's date and the line "Check the sourdough starter." Set this up so it runs on its own. |
A Gmail task was planned and left out, because we would only run it on a test account and none was ready.
How each result was scored
Every task has four checks, and a script decides each one from the files and the answer, not from how the work looks. A score is the number of checks passed, out of 4.
| Task | The four checks |
|---|---|
| Poster | An image file was saved · it is 1080 by 1350 · the date, address and headline are in it · it is not one of Pragma's ready-made templates |
| Video | A video file was saved · it plays · about 6 seconds and vertical · not a template |
| Website | A page file was saved · it opens in a browser · the hours and address are on the page · not a template |
| PDF report | A PDF was saved · two pages · the numbers are right · it has a chart |
| Web search | It answered · the number is right · sources given · the links work |
| Spreadsheet | An .xlsx was saved · the total uses a formula · the total is right · it has a chart |
| Remember | It answered · the facts are right · in a new chat · no guessing |
| Find a file | It answered · the amount is right · it says where the file is · it found the October invoice, not the September one |
| Schedule | A schedule was set up · it ran on its own · the right line · with the date |
Two more checks run beside the scores. One marks any output built from a template Pragma ships, so a template never counts as the model's own work. The other reads the run's full record for work done by a different model (an image service, say). For this benchmark the local models had to make every picture themselves, and none of their runs used another model.
Results: free AI on this computer
Each cell is the average score out of 4, then how many runs passed all four checks, then the typical time.
| Task | Qwen 35B, plain chat | Qwen 35B, in Pragma | Qwen 9B, plain chat | Qwen 9B, in Pragma |
|---|---|---|---|---|
| Poster | 0 (0 of 3), 39 s | 3.7 (2 of 3), 6 min | 0 (0 of 1) | 4 (1 of 1), 6 min |
| Video | 0 (0 of 3) | 3.0 (0 of 3), template | 0 (0 of 1) | 4 (1 of 1), 76 s |
| Website | 0 (0 of 3) | 4 (3 of 3), 30 to 56 min | 0 (0 of 1) | 4 (1 of 1), 20 min |
| PDF report | 0 (0 of 3) | 4 (3 of 3), 4 min | 0 (0 of 1) | 3 (0 of 1) |
| Web search | 2.3 (0 of 3) | 2.7 (1 of 3) | 0 (0 of 1) | 3 (0 of 1) |
| Spreadsheet | 0 (0 of 3) | 2.7 (0 of 3) | 0 (0 of 1) | 3 (0 of 1) |
| Remember | 0 (0 of 3) | 2.7 (2 of 3) | 0 (0 of 1) | 4 (1 of 1) |
| Find a file | 0 (0 of 3) | 1.3 (1 of 3) | 0 (0 of 1) | 0 (0 of 1) |
| Schedule | 0 (0 of 3) | 0.7 (0 of 3) | 0 (0 of 1) | 1 (0 of 1) |
In a plain chat the model can only write words, so every file task scores zero there. Asked for a post or a PDF, it said it cannot make files and offered a plan to follow in Canva or Word. Asked for a website, it wrote the code for you to save yourself; pasted into a file by hand, that code would have passed all four checks. Qwen Code, the agent on its own, made a post too (3 of 4, square): part of the lift is having any agent at all, and the rest is what Pragma adds around it.
Results: Codex and Antigravity
| Task | Codex alone | Codex in Pragma | Antigravity alone |
|---|---|---|---|
| Poster | 2 (0 of 3), 2 min | 4 (3 of 3), 4 min | 2 (0 of 2) |
| Video | 4 (3 of 3), 26 min | 3 (0 of 3), template | 4 (1 of 1) |
| Website | 4 (3 of 3), 4 min | 4 (3 of 3), 16 min | 4 (1 of 1) |
| PDF report | 4 (3 of 3) | 4 (3 of 3) | 4 (1 of 1) |
| Web search | 3 (0 of 3) | 3 (0 of 3) | 4 (1 of 1) |
| Spreadsheet | 4 (3 of 3) | 4 (3 of 3) | 4 (1 of 1) |
| Remember | 0 (0 of 3) | 4 (2 of 2) | 4 (1 of 1) |
| Find a file | 4 (3 of 3) | 4 (2 of 2) | 4 (1 of 1) |
| Schedule | not run | 4 (2 of 2) | not run |
A strong cloud model already does most of these on its own, and the table shows it. Pragma's difference for Codex is in three places: it holds the job's rules (every post at the size asked for), it carries memory between chats, and it can run work on a schedule. It also costs time on websites, where Pragma asks a few questions and reviews the page before saying done.
Find reference: does design research make better pages?
Find reference is a Pragma talent that does a designer's research for you. While you answer a website's questions, it studies award-winning sites for that kind of business (Awwwards, Httpster, One Page Love, Made in Webflow, Supahero and others), curates the strongest ideas, and works out which look, type and layout would suit your brand before it proposes a design. The page itself is always made new for you. To test it we had Codex in Pragma build three sites three times each, once with Find reference and once without: a bakery, a dental clinic and a law firm.
A separate AI then judged each pair blind. It saw both pages unlabelled, scored them on first impression, fit for the business, type, layout and originality, and picked one. Every pair was judged twice, with the sides swapped, so a page only wins both judgings if it is better from either side.
| Site | With Find reference | Without |
|---|---|---|
| Dental clinic | 6 | 0 |
| Law firm | 4 | 2 |
| Bakery | 2 | 4 |
| All three | 12 | 6 |
What this does not show
We would rather you hear these from us.
- Small numbers. Most cells are three runs; the 9B model and Antigravity are one. Treat the scores as what we saw, not as percentages.
- The PDF chart check was too loose. It passed any chart-like block, and Qwen's three PDFs had text bars, a broken image or no chart instead of a drawn one. Judged strictly, the free model's PDFs score 3 of 4, not 4.
- Videos. Qwen 35B and Codex in Pragma used Pragma's count-up video template, so those runs are marked as template work and do not count as the model's own. Qwen 9B made its own.
- Web search for local models. Pragma does not give a model on your computer a web search tool yet, so Qwen answered from memory.
- Schedules and file search with local models are unreliable today (0.7 and 1.3 of 4).
- Teams. We also ran three companions in one room against one strong model alone. The room stalled at a hand-off and the Antigravity account then ran out of quota, so that test is inconclusive and not reported here.
- One computer, one day. Different hardware, models or wording will give different numbers.
We kept every output and the scripts that scored them. If you want the raw files for a task, ask in the community.